Llama 2 70B vs Zephyr-7B LLM models compared
The new Zephyr-7B AI model has been fine-tuned from Mistral-7B-v0.1 and beats llama-2 70B LLM on the MT Benchmark. Llama 2 70B vs Zephyr-7B
Source: geeky-gadgets.com
Stay updated with breaking news from Direct Preference Optimization. Get real-time updates on events, politics, business, and more. Visit us for reliable news and exclusive interviews.

The new Zephyr-7B AI model has been fine-tuned from Mistral-7B-v0.1 and beats llama-2 70B LLM on the MT Benchmark. Llama 2 70B vs Zephyr-7B
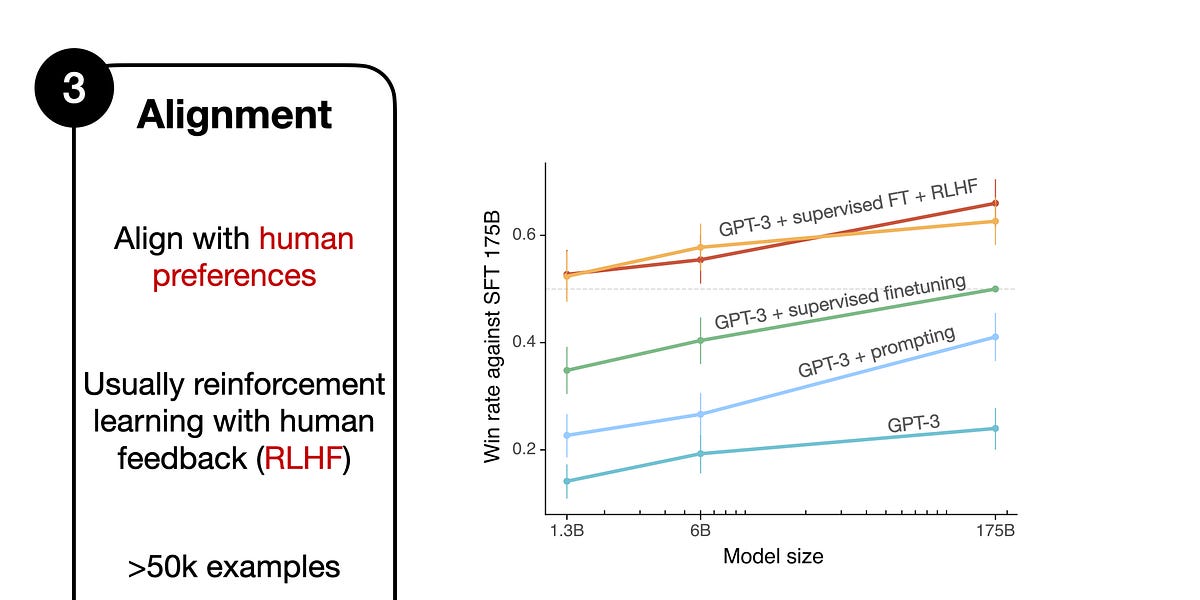
I frequently reference a process called Reinforcement Learning with Human Feedback (RLHF) when discussing LLMs, whether in the research news or tutorials. RLHF is an integral part of the modern LLM training pipeline due to its ability to incorporate human preferences into the optimization landscape, which can improve the model's helpfulness and safety.