New Stable Cascade model by Stability AI aims to enhance AI-driven art
Stable Cascade is the new model designed by Stability AI to transform the landscape of AI-driven image generation.
Source: readwrite.com
Stay updated with breaking news from Preference Optimization. Get real-time updates on events, politics, business, and more. Visit us for reliable news and exclusive interviews.

Stable Cascade is the new model designed by Stability AI to transform the landscape of AI-driven image generation.

Explore the significant AI advancements, impactful partnerships, and legal debates that defined 2023.
Course to get into Large Language Models (LLMs) with roadmaps and Colab notebooks. - GitHub - mlabonne/llm-course: Course to get into Large Language Models (LLMs) with roadmaps and Colab notebooks.
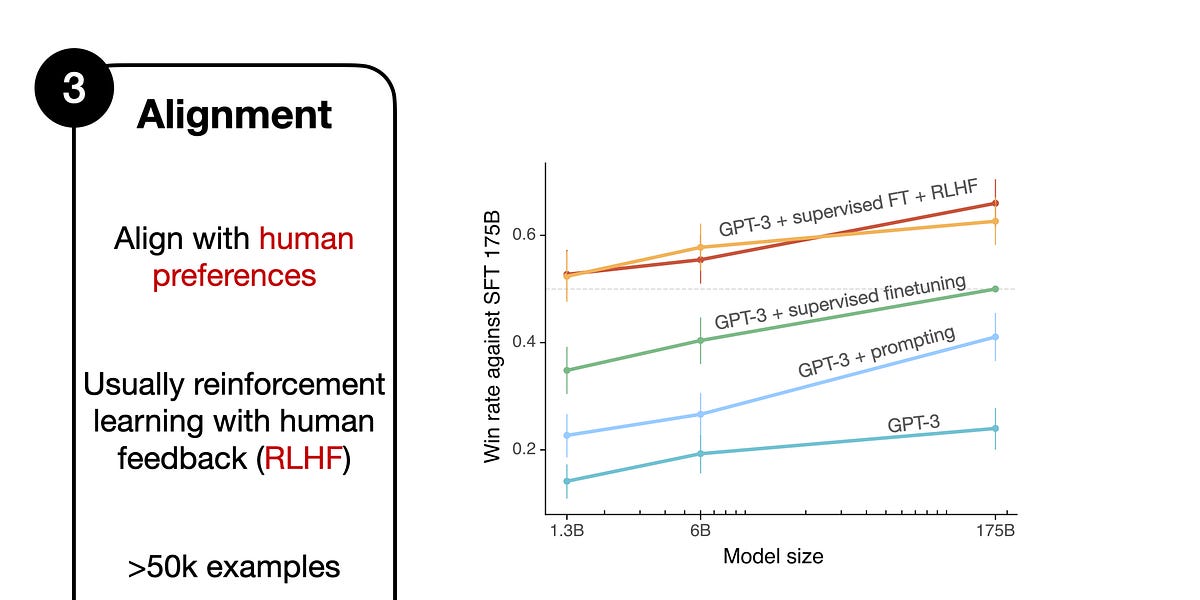
I frequently reference a process called Reinforcement Learning with Human Feedback (RLHF) when discussing LLMs, whether in the research news or tutorials. RLHF is an integral part of the modern LLM training pipeline due to its ability to incorporate human preferences into the optimization landscape, which can improve the model's helpfulness and safety.

Open-source tool for data-centric NLP