Microsoft's New AI Tool Can Mimic Voices With 3 Seconds of Audio
VALL-E can preserve the original speaker's emotional tone and even simulate their acoustic environment.
Source: gizmodo.com
Stay updated with breaking news from Speaker Recognition. Get real-time updates on events, politics, business, and more. Visit us for reliable news and exclusive interviews.
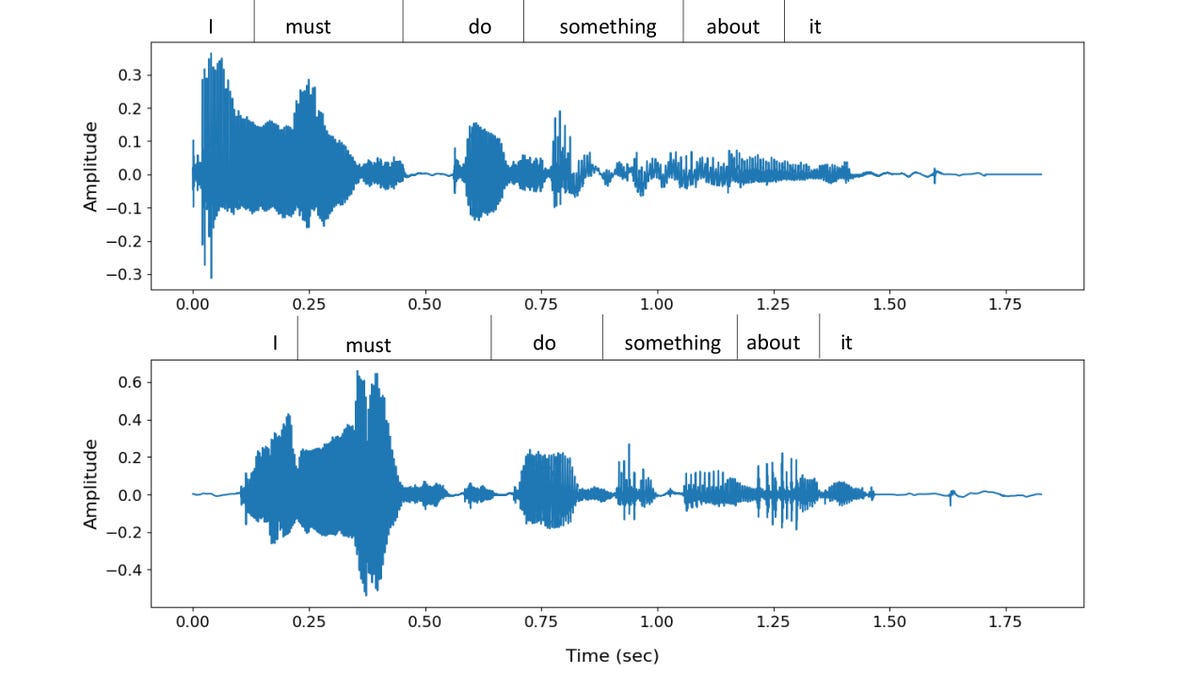
VALL-E can preserve the original speaker's emotional tone and even simulate their acoustic environment.

UZH and ZHAW offer Certificate in Advanced Studies in Translation Technology and AI. Registration now open.

Microsoft Is Reportedly in Talks to Scoop Up AI Firm Nuance Communications for $16 Billion Photo: Jeenah Moon (Getty Images) Microsoft is in advanced talks to acquire Nuance Communications, an artificial intelligence firm whose speech recognition tech helped develop Apple’s Siri virtual assistant, for as much as $16 billion, a source familiar with the matter told Reuters. Advertisement The deal price being negotiated could value Nuance at around $56 per share, the source said, a roughly 23% premium compared to the share’s closing price on Friday. They added that an official announcement ...
Components more than together ultimately speaker recognition with human in the loop. that's another term. >> you always have a trained examiner listening? >> that is correct. >> your examiners are trained in the various methodologist available for speaker recognition? >> that is correct. the computer cannot really assess whether, you know, inputting voices produce inference or computer cannot tell whether a person was happy, sad or voice was you know produced under, you know, normal duress. so to detect all of those, we have to depend up on the trained examiners. >> all right. we will step awa...