Vimarsana
Biggest News Aggregation in the World

Page 37 - Language Model News Today : Breaking News, Live Updates & Top Stories | Vimarsana

Stay updated with breaking news from Language Model. Get real-time updates on events, politics, business, and more. Visit us for reliable news and exclusive interviews.

Top News In Language Model Today - Breaking & Trending Today

Charting the Future of Data Storage: DSPA-Asia Bootcamp by GreaterHeat - Vimarsana News

Charting the Future of Data Storage: DSPA-Asia Bootcamp by GreaterHeat

GreaterHeat, a Singapore-based AI and Web3 technology company, has concluded its highly successful Second Cohort of the Decentralized Storage Providers Accelerator Asia (DSPA-Asia) Bootcamp from September 11-12, 2023, taking place during Singapore Blockchain Week, which runs from September 11 to September 17, 2023.In collaboration with Protocol Labs, the pioneering tech

New Competitor To Google's Palm 2? - Vimarsana News

New Competitor To Google's Palm 2?

Hugging Face has recently introduced Falcon 180B, the largest open-source Language Model (LLM) with no guardrails.

AI app Character.ai is catching up to ChatGPT in the US - Vimarsana News

AI app Character.ai is catching up to ChatGPT in the US

Character.ai, the AI app maker that lets users design their own AI characters, is catching up to ChatGPT in terms of mobile app usage. According to a

Meta Is Apparently Developing a Secret, Powerful New AI - Vimarsana News

Meta Is Apparently Developing a Secret, Powerful New AI

Second Wind As OpenAI and Google sprint ahead in the ongoing Silicon Valley AI race, Meta appears more determined than ever to catch up. According to new reporting from The Wall Street Journal, Meta-formerly-Facebook is secretly developing a powerful new AI model designed to compete with OpenAI's GPT-4, the most advanced iteration of the rival […]

Source: yahoo.com
LLM Training: RLHF and Its Alternatives - Vimarsana News

LLM Training: RLHF and Its Alternatives

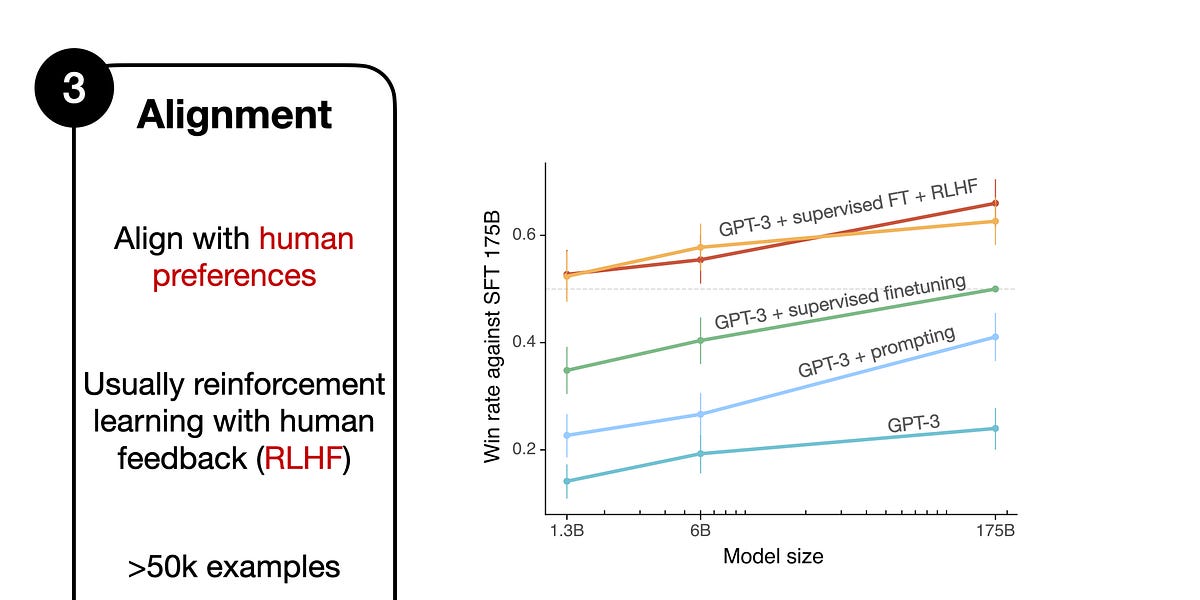
I frequently reference a process called Reinforcement Learning with Human Feedback (RLHF) when discussing LLMs, whether in the research news or tutorials. RLHF is an integral part of the modern LLM training pipeline due to its ability to incorporate human preferences into the optimization landscape, which can improve the model's helpfulness and safety.