McIntosh's bonkers quad-driver subwoofer will cost $50,000
The McIntosh PS2K is a towering collection of four 13-inch drivers powered by 2,000 watts of class D amplification.
Source: digitaltrends.com
Stay updated with breaking news from Signal Processing. Get real-time updates on events, politics, business, and more. Visit us for reliable news and exclusive interviews.
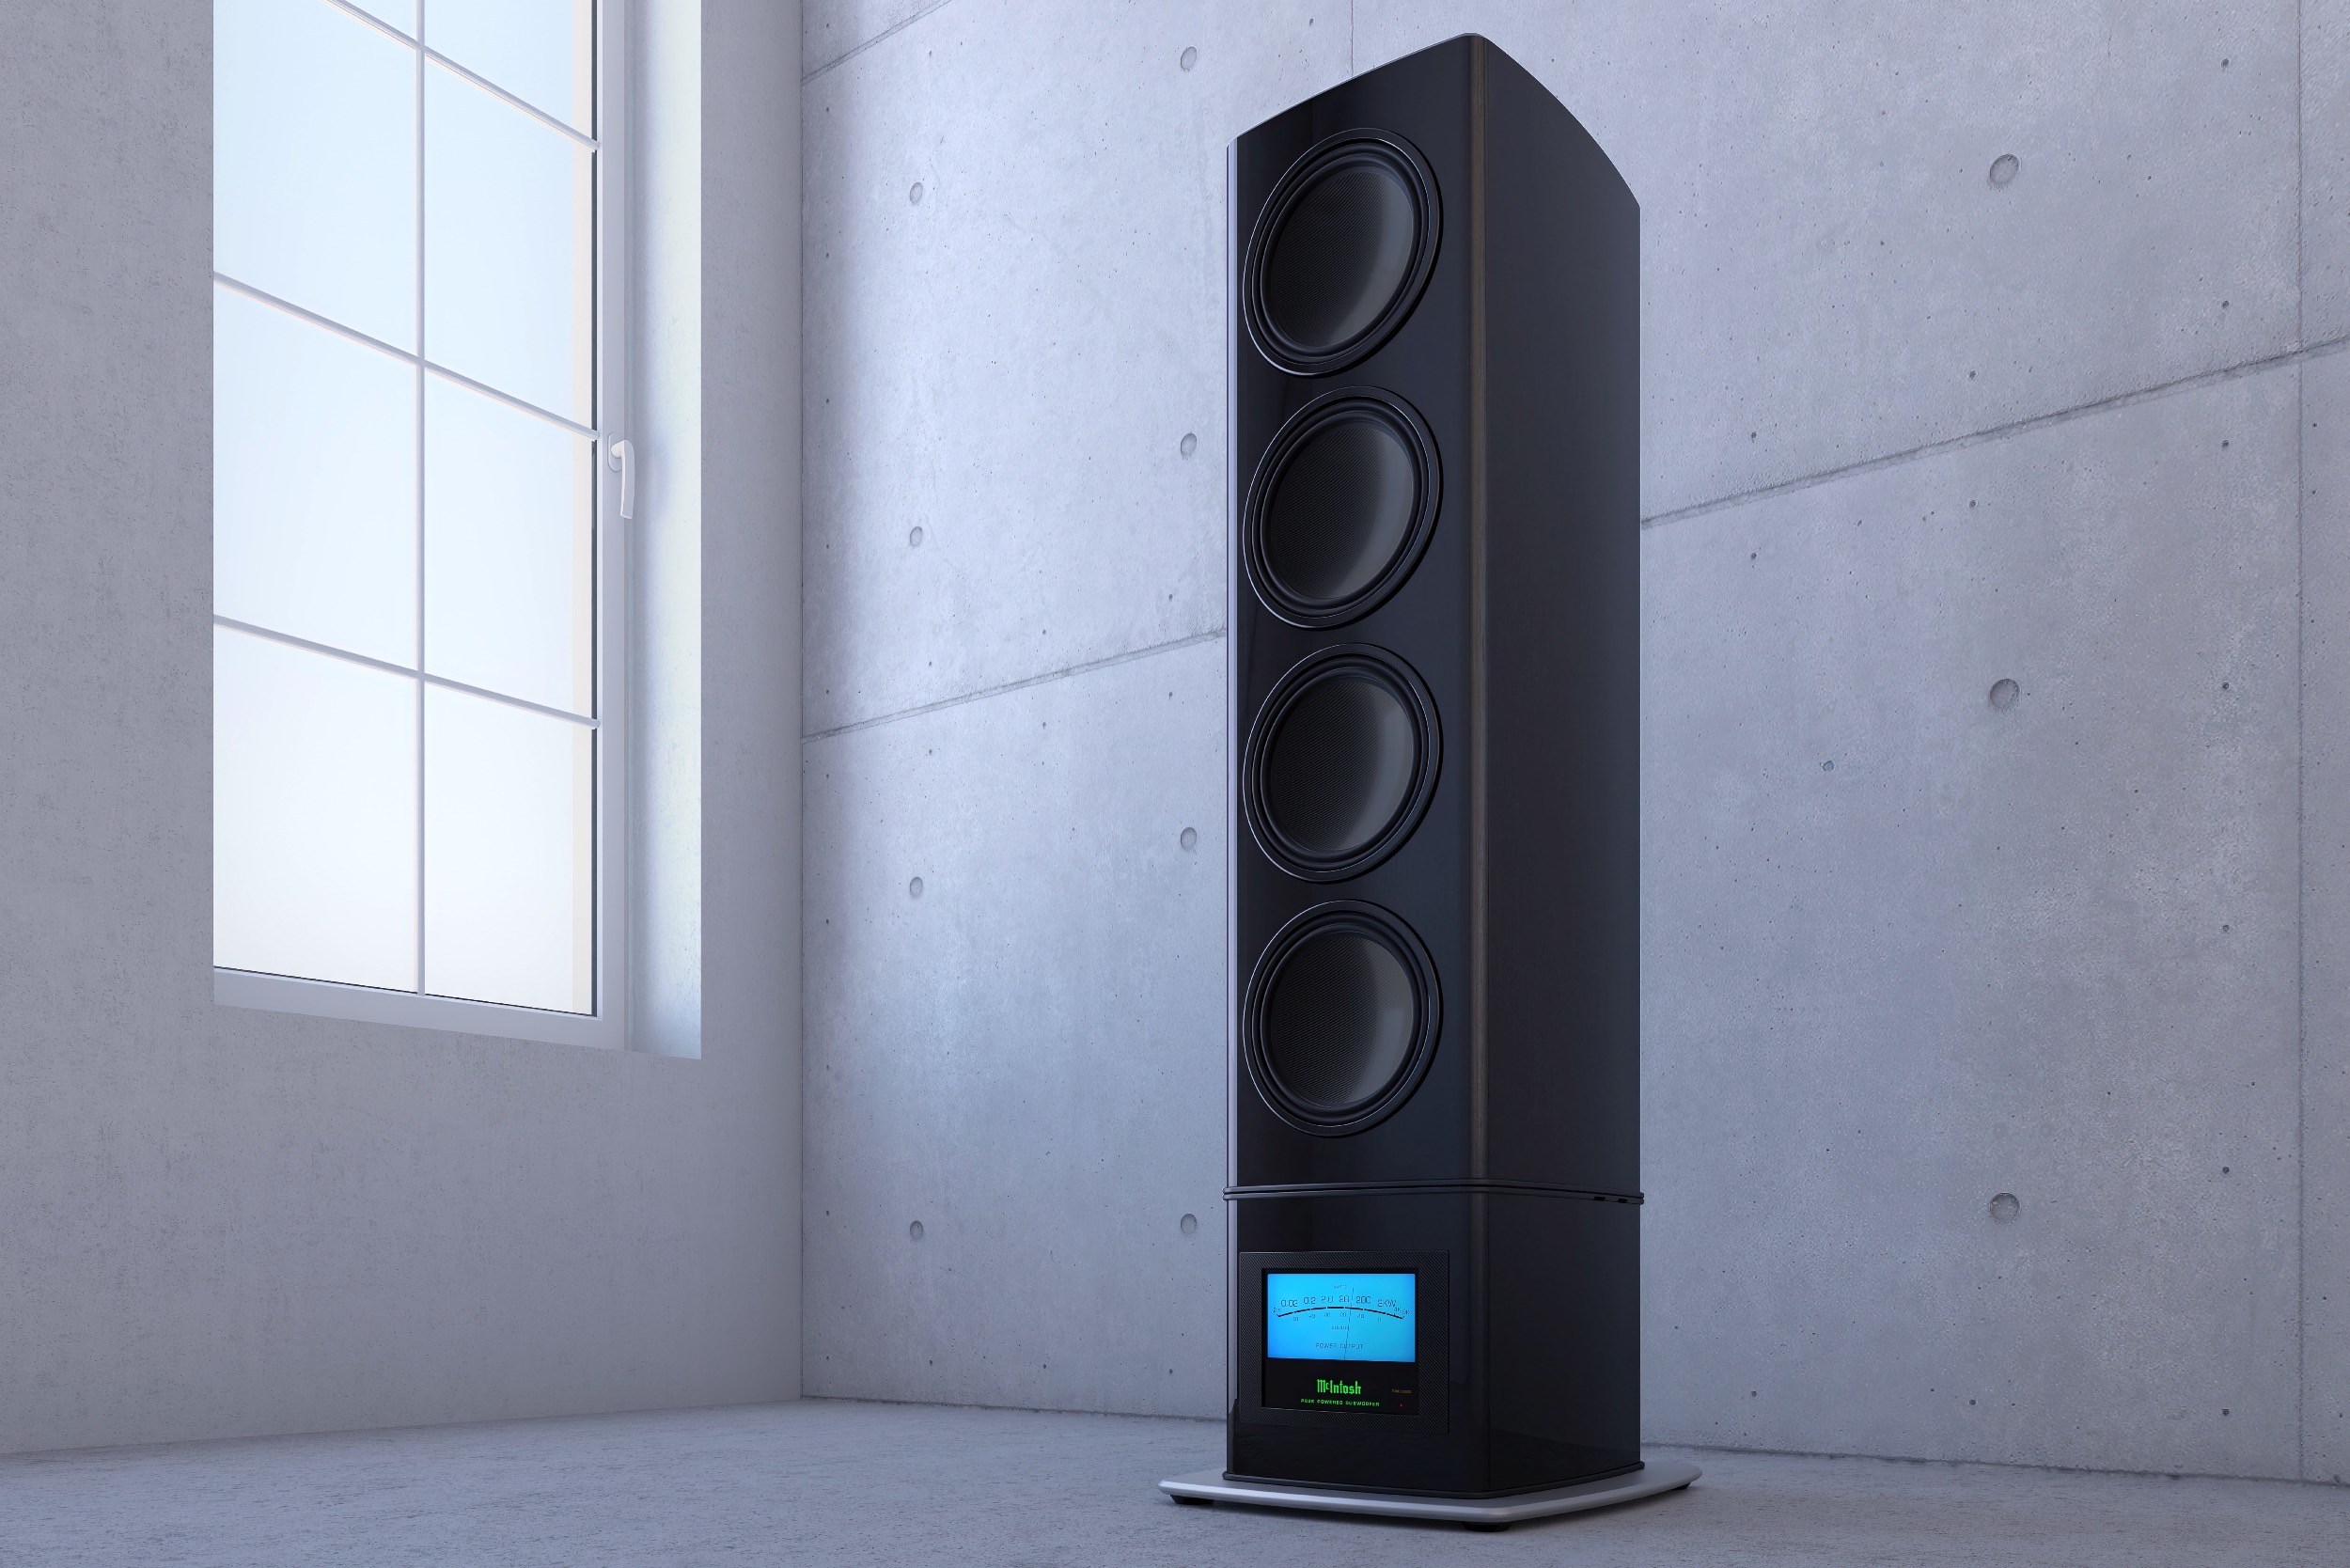
The McIntosh PS2K is a towering collection of four 13-inch drivers powered by 2,000 watts of class D amplification.
Recurrent neural networks are a classification of artificial neural networks used in artificial intelligence (AI), natural language processing (NLP), deep learning, and machine learning.

New Castle, Delaware, Sept. 05, 2023 (GLOBE NEWSWIRE) -- Allied Market Research published a report, titled, "Smart Dust Market By Type (Microelectromechanical Sensors (MEMS), Robots, and Others), Component (Sensors,
The MoU was exchanged between Shri R A Govardhan, Officiating Director, DIQA and Prof B S Murty, Director, IITH

Speech neuroprostheses have the potential to restore communication to people living with paralysis, but naturalistic speed and expressivity are elusive1. Here we use high-density surface recordings of the speech cortex in a clinical-trial participant with severe limb and vocal paralysis to achieve high-performance real-time decoding across three complementary speech-related output modalities: text, speech audio and facial-avatar animation. We trained and evaluated deep-learning models using neural data collected as the participant attempted to silently speak sentences. For text, we demonstrate...