TikTok's 'Bold Glamour' and 'Teenage Look' Filters Are Terrifying Its Audience
The two TikTok filters are incredibly convincing attempts at changing your face, and they could be fueled by machine learning.
Source: gizmodo.com
Stay updated with breaking news from Filter Theory. Get real-time updates on events, politics, business, and more. Visit us for reliable news and exclusive interviews.
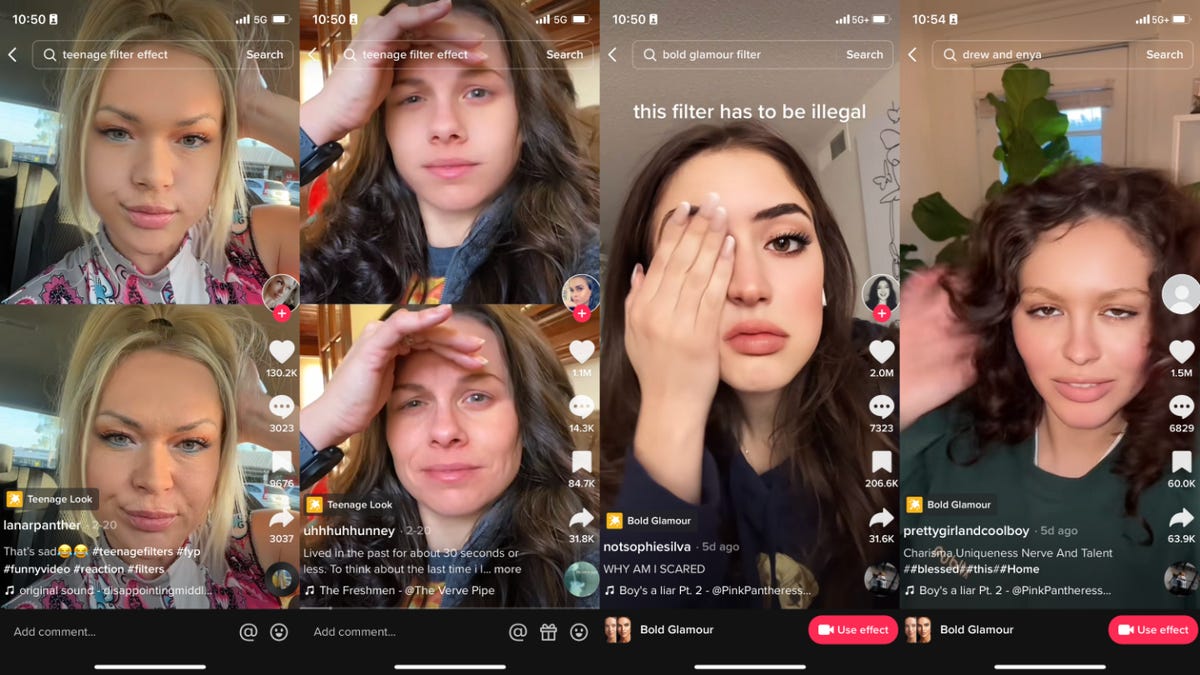
The two TikTok filters are incredibly convincing attempts at changing your face, and they could be fueled by machine learning.

Finally, Black TikTokers can join in on the fun of filters

You too can get big anime boobs if you have a pair of bowls, pans, or any other rotund household objects on hand

New Yorker Electronics Distributes High Quality Crystals, Oscillators, Antennas and High End Frequency Management Products to Expanded Markets
Incremental Risk Minimization Algorithm Incremental Regression with Polynomials ↑ Incremental (or on-line) learning regression is the process of adapting a model one example at a time without accumulating a batch of data. It has the advantages of allowing continuous adaptation to non-stationary environments, easily handling big data through stream processing, and a fixed low computation and memory demand. The easiest solution is to perform a gradient descent on a squared error metric with each new training example. But this solution does not work well for complex model struc...